 Dochemist
The Document
Alchemist.
Transform unstructured documents into structured, actionable data — with visual pipelines built for modern operations. Launching soon.
Three steps to structured data
Upload
Drop PDFs, images, or office files. Batch upload thousands at once.
Build Pipeline
Design extraction flows visually with our drag-and-drop node builder.
Get Structured Data
Receive clean JSON via webhook or API, with full source citations.
Visually Orchestrate
Your Data Flow
Design sophisticated extraction pipelines on an intuitive canvas. Connect intelligent nodes to ingest, parse, route, and transform — no brittle code required.
- Intelligent Routing
Branch workflows in real-time based on document content rules.
- Custom Transformations
Reshape raw outputs into your exact JSON schema before delivery.
- Batch Ingestion
Process thousands of documents simultaneously with robust queues.
Precision Extraction
with Built-In Trust
State-of-the-art vision and language models extract layout, text, and nested tables — every data point traced back to source.
- Source Citations
Every field mapped to its bounding box on the original document.
- Confidence Scoring
Field-level metrics to automatically flag uncertain extractions.
- Markdown & HTML Tables
Preserve complex tabular layouts perfectly during extraction.
Automation, Guided by
Human Expertise
Insert approval gates directly into pipelines. When confidence dips below your threshold, the workflow pauses — your team reviews, approves, or rejects before data moves forward.
Waiting approval
Suspendedgate_confidence_check
Claim amount exceeds $10,000 threshold. Manual review required before proceeding with extraction pipeline.
Secure, Scalable, and
Ready to Integrate
Built for high-performance operations. Fits securely into your existing stack.
- Granular Access Control
Manage organizations, projects, and member roles — Admin, Editor, Viewer.
- Transparent Billing
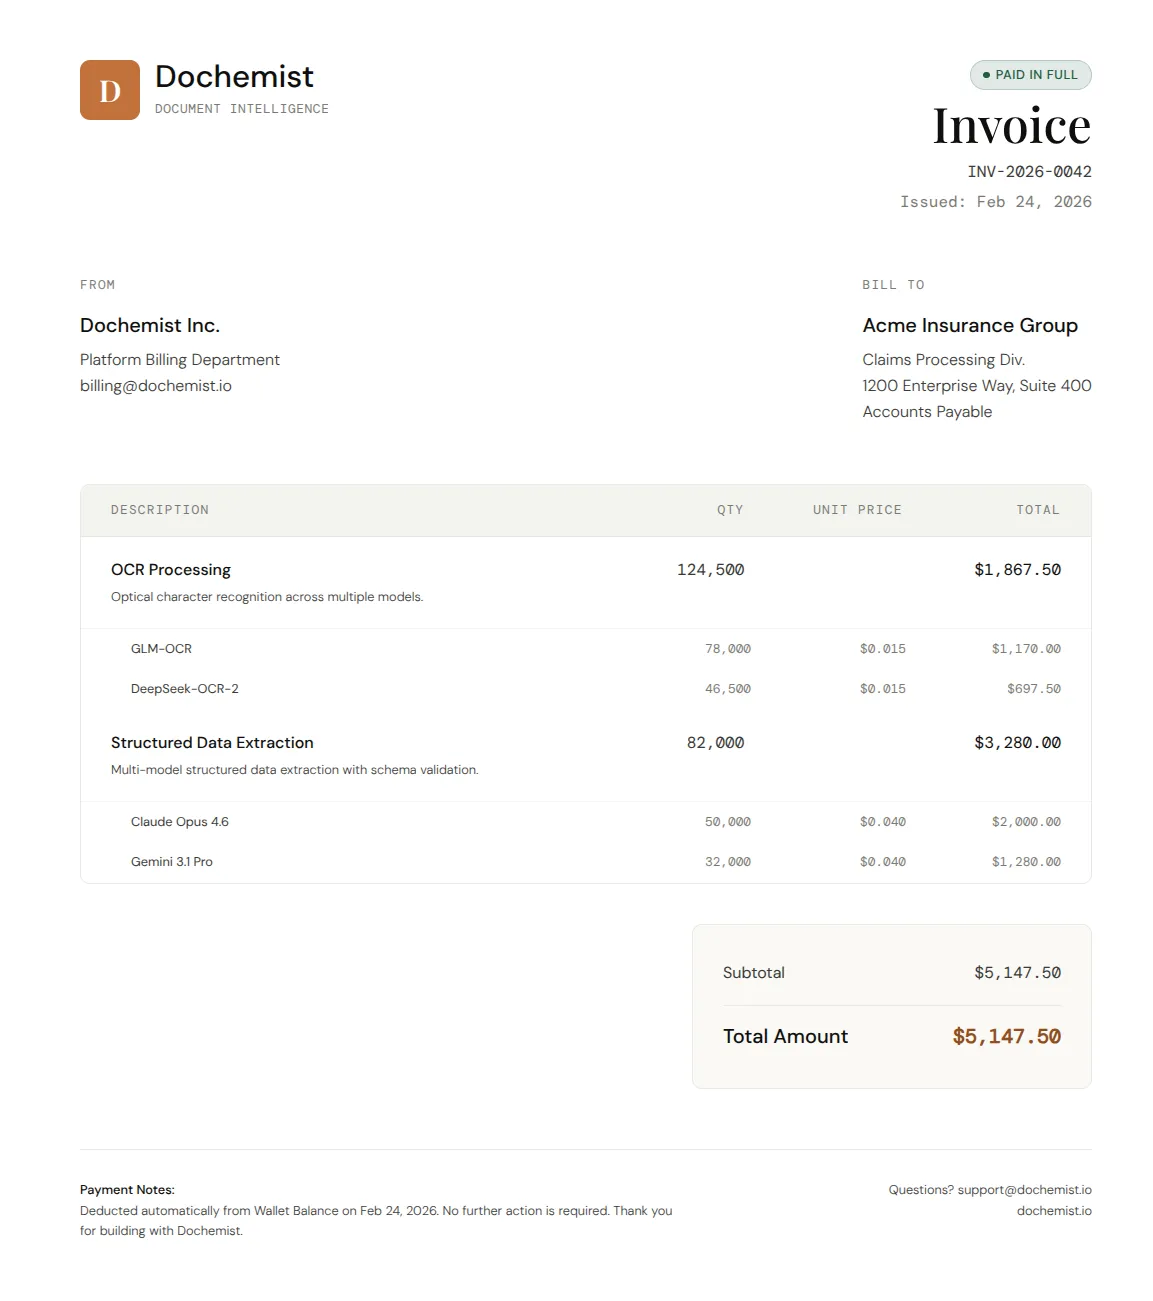
Pay per page — starting from $0.001. HITL reviews and webhooks are always free. See pricing.
- Real-Time Webhooks
Sync parsed data and events to your backend via embedded webhook portal.
- API & SDKs
Integrate programmatically with official Python and Node.js libraries, or call the REST API directly.
The Latest Models,
One Unified Output
We deploy frontier document intelligence models the moment they launch — so you always extract with the most capable technology available.
GLM-OCR
The highest-ranked document intelligence model available today. Exceptional at parsing complex tables, mathematical formulas, and extracting structured data from real-world business documents.
DeepSeek-OCR-2
A powerful multilingual model that handles complex page layouts, multi-column documents, and converts pages to clean Markdown — ideal when your documents span many languages and formats.
These are just our featured models. Dochemist supports a growing catalogue of document intelligence models — we add new ones as they prove themselves in production.
Switch between models freely — every model returns the same standardized JSON schema. Full transparency on per-model pricing and capabilities so you choose the right tool for each job.
Pay per Page,
Nothing More
Two metered services, one simple rate. Parsing and Structured Data Extraction start from $0.001 per page — everything else is free.
All prices are indicative and subject to change before general availability. Final pricing will be published at launch. Model-specific rates may vary — see the model card for details.
Top up your balance and spend as you go. No minimums, no commitments.
Full visibility into spend per pipeline, model, and document type.
Higher volumes unlock lower per-unit rates automatically.
Connect to the Tools
Your Team Already Uses
Integrate Dochemist into your stack with official SDKs, a RESTful API, and real-time webhooks — no middleware required.
REST API & SDKs
Call the Dochemist API directly or use our official Python and Node.js SDKs to parse documents, run extractions, and retrieve results — all from your own codebase.
Webhooks
Receive structured JSON the moment a document is processed. Push events to Salesforce, Xero, ERP systems, or your own backend — no polling required.
Be first in line.
We're building Dochemist in the open. Join the waitlist and we'll notify you the moment early access opens.